

- Nvidia and OpenAI have partnered to let powerful AI models run locally on personal computers.
- If you have an Nvidia GeForce RTX or RTX Pro graphics card, you can use models like gpt-oss-20b and gpt-oss-120b without internet or a subscription.
- For home use, the gpt-oss-20b model needs a GPU with at least 16GB of VRAM.
Yesterday, Nvidia announced a collaboration with OpenAI. This partnership with OpenAI enables powerful LLM models such as gpt-oss-20b and gpt-oss-120b to run locally. These models are perfect for advanced reasoning, assisted coding, intelligent search, and document analysis.
So, if you own a Nvidia GeForce RTX or RTX Pro graphics card, you should be aware that advanced AI models are now available without a subscription. Furthermore, no internet connection is required.
This collaboration between Nvidia and OpenAI allows developers and enthusiasts to operate generative AI locally for faster, more private, and cloud-free performance. This is terrific news if you work in offline contexts or want complete control over your models.

For home, the gpt-oss-20b is the ideal choice. However, much as with gaming, you’ll need at least a GPU with 16GB of VRAM. A GeForce RTX 4080 or above is preferred. Local throughput is approximately 256 tokens per second on systems equipped with a GeForce RTX 5090.
For enterprise and server applications, gpt-oss-120b requires a GPU with at least 80GB of VRAM; hence, Nvidia Blackwell server GPUs are essential. On platforms such as the GB200 NVL72, they may process up to 1.5 million tokens per second, allowing for tens of thousands of concurrent users.
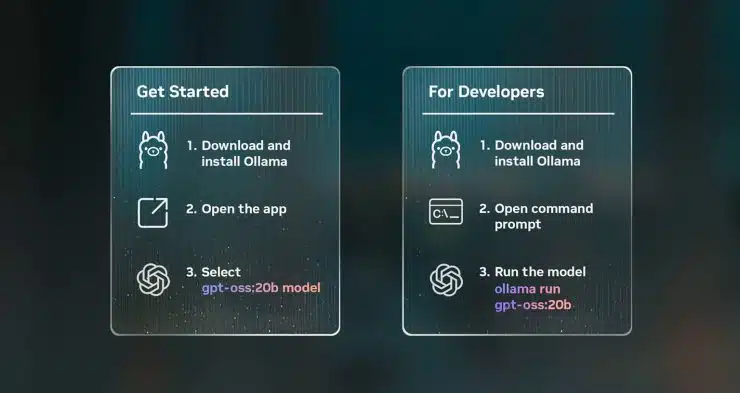
Ollama: The most straightforward approach is to use these templates. Simply select one and begin a chat without any additional settings. It also supports PDFs, multimodal prompts, and customisable context.
Microsoft AI Foundry Local: enables you to leverage models using commands or SDK integrations. It is built on ONNX Runtime and uses CUDA and TensorRT to take full advantage of RTX GPUs.
llama.cpp: For advanced users, Nvidia works with the open-source community to provide optimisations like Flash Attention, CUDA Graphs, and support for the new MBFP4 format.
Thank you! Please share your positive feedback. 🔋
How could we improve this post? Please Help us. 😔

[Editor-in-Chief]
Sajjad Hussain is the Founder and Editor-in-Chief of Tech4Gamers.com. Apart from the Tech and Gaming scene, Sajjad is a Seasonal banker who has delivered multi-million dollar projects as an IT Project Manager and works as a freelancer to provide professional services to corporate giants and emerging startups in the IT space.
Majored in Computer Science
13+ years of Experience as a PC Hardware Reviewer.
8+ years of Experience as an IT Project Manager in the Corporate Sector.
Certified in Google IT Support Specialization.
Admin of PPG, the largest local Community of gamers with 130k+ members.
Sajjad is a passionate and knowledgeable individual with many skills and experience in the tech industry and the gaming community. He is committed to providing honest, in-depth product reviews and analysis and building and maintaining a strong gaming community.
 Join Our Community